RAG AI Framework for Beginners: How It Uses Business Files
Categories
- Agentic AI (14)
- AI (1)
- AI & Automation (3)
- AI & Technology (1)
- AI Adoption (1)
- AI Automation (9)
- AI Business Solutions (1)
- AI Consulting (1)
- AI Costs & Pricing (1)
- AI Development (3)
- AI Framework (1)
- AI Governance & Compliance (1)
- AI in Enterprise (3)
- AI Services Canada (1)
- AI Strategy (2)
- AI Use Cases (1)
- AI/ML Services (1)
- Artificial Intelligence (7)
- Artificial Intelligence Canada (2)
- Best AI Agents in 2026 (2)
- Business Automation (2)
- Business Technology (4)
- Business Technology Canada (1)
- Canada Tech & Business (3)
- Case Studies (1)
- Cloud Computing (1)
- CRM Automation (1)
- Custom Development (2)
- Custom Software Development (2)
- Custom Software Development Company (2)
- Customer Support (2)
- DevOps (1)
- Devops & Cloud Services (1)
- DevOps Services (1)
- Digital Transformation (5)
- ERP Technology (3)
- Hiring Guide (1)
- Industry Insights (2)
- Kubernetes (1)
- LLM Integration services (1)
- Local Business Guides (1)
- Machine Learning (1)
- Ontario Tech (1)
- Productivity (1)
- Python Development (1)
- RAG AI Framework (1)
- Software Development (2)
- Software Engineering (1)
- Tech Product Pricing (1)
- Web Development (1)
Recent Posts
- All Posts
- Agentic AI
- agentic AI customer support
- AI
- AI & Automation
- AI & Technology
- AI Adoption
- AI Automation
- AI Business Solutions
- AI Consulting
- AI Costs & Pricing
- AI Development
- AI Framework
- AI Governance & Compliance
- AI in Enterprise
- AI Services Canada
- AI Strategy
- AI Use Cases
- AI/ML Services
- Artificial Intelligence
- Artificial Intelligence Canada
- Best AI Agents in 2026
- Business Automation
- Business Technology
- Business Technology Canada
- Canada Tech & Business
- Case Studies
- Cloud Computing
- CRM Automation
- Custom Development
- Custom Software Development
- Custom Software Development Company
- Customer Support
- DevOps
- Devops & Cloud Services
- DevOps Services
- Digital Transformation
- ERP Technology
- Hiring Guide
- Industry Insights
- Kubernetes
- LLM Integration services
- Local Business Guides
- Machine Learning
- Ontario Tech
- Productivity
- Python Development
- RAG AI Framework
- Software Development
- Software Engineering
- Tech Product Pricing
- Web Development
- Back
- Generative AI
Author: Python Technologies Date: 10/12/2026
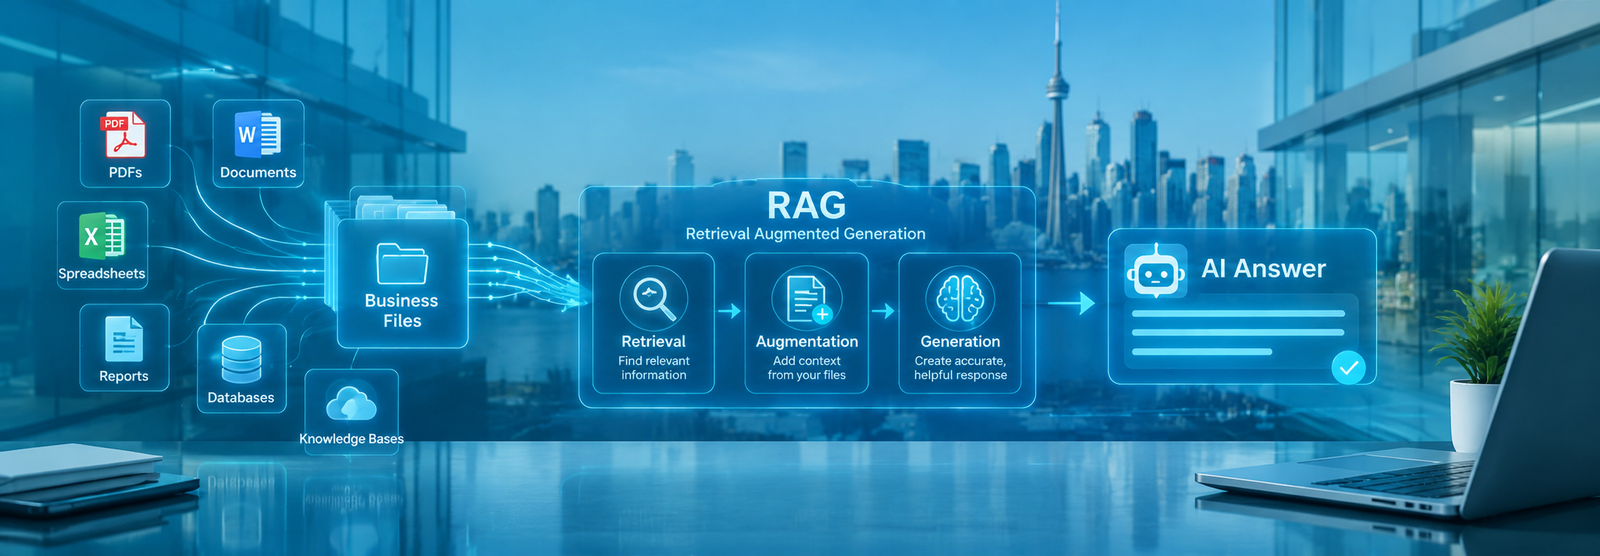
A RAG AI framework lets an AI model search through your own business documents and give you accurate, up-to-date answers, instead of guessing from old training data. RAG stands for Retrieval-Augmented Generation. It connects a language model to a live knowledge base, so the AI finds the right information first and then forms a response from what it finds.
Canadian businesses use this framework to answer questions from HR policies, legal contracts, product manuals, customer records, and internal wikis, without retraining the AI model from scratch.
This guide explains exactly what Retrieval-Augmented Generation is, how the pipeline works step by step, when it makes sense for your business, and how it compares to other approaches like agentic AI and MCP. No technical background required.
What Is a RAG AI Framework?
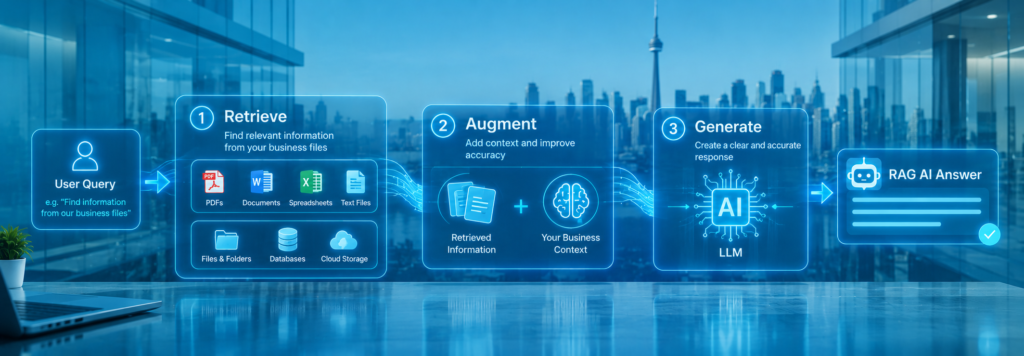
A Retrieval-Augmented Generation framework is a system that has two main parts working together.
The first part is a retrieval engine. This engine searches through documents, databases, or files you give it. It finds the chunks of text most relevant to the question being asked.
The second part is a language model. This is the AI that reads the retrieved text and writes a response in plain language.
When you ask a question, the system does not rely on what it learned during training. It goes and fetches the right information from your actual files, and then generates an answer based on that fresh content.
This matters because standard AI models have a knowledge cutoff. They do not know what happened after a certain date. They do not know your company policies, your product details, or your customer history. This framework solves this by giving the AI model access to your documents at the moment of each query.
Python Technologies builds custom RAG AI solutions and LLM integration services for businesses across Canada. The team has shipped AI products used by hundreds of thousands of users, and RAG architecture is one of the most requested foundations.
How the RAG Pipeline Works
The Retrieval-Augmented Generation pipeline has five stages. Each stage is essential. Skipping one creates gaps in accuracy.
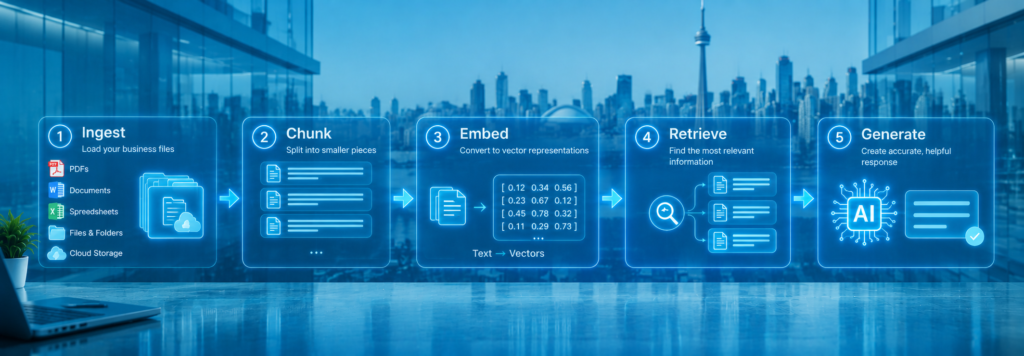
Stage 1: Document Ingestion
Your business files get loaded into the system. This includes PDFs, Word documents, spreadsheets, help desk tickets, Slack threads, Confluence pages, CRM notes, and anything else your team uses. The RAG system reads them all and prepares them for indexing.
Stage 2: Chunking
Each document gets broken into smaller pieces called chunks. Chunking strategies for RAG matter because the size and shape of each chunk affects how well the retrieval step works. Too large and the chunks carry too much noise. Too small and they lose context. Most production systems use overlapping chunks between 256 and 512 tokens.
Stage 3: Embedding
Each chunk gets converted into a vector, which is a list of numbers that captures the meaning of the text. This is done by an embedding model. Similar pieces of text end up with similar vectors. This is what allows the retrieval engine to find semantically related content, not just keyword matches.
Stage 4: Retrieval
When a user sends a question, the question also gets converted into a vector. The system searches the vector database for chunks whose meaning is close to the question. Modern RAG systems use hybrid search RAG, which combines dense vector search with sparse keyword search (BM25) to get better results. A cross encoder reranker then sorts the top matches by relevance before sending them to the language model.
Python Technologies uses this exact retrieval architecture when building agentic AI systems that need to pull from large internal knowledge bases accurately.
Stage 5: Generation
The language model receives the retrieved chunks alongside the user’s question. It reads the context and generates a grounded answer, citing only what is in those documents. This is how the framework reduces hallucination. The model is not invented. It is summarizing what it was given.
Why Canadian Businesses Choose This Framework
Most Canadian businesses do not have millions of dollars to train a private AI model from scratch. This framework is the practical alternative. It gives you a highly capable AI that knows your business deeply, without requiring model training.
Here are the most common reasons Canadian companies adopt this approach.
- Accuracy on company-specific questions. A general AI model cannot tell you what your return policy says or what the SLA in your client contract specifies. A system that has indexed your documents can answer both questions correctly and point to the source.
- Keeps data private. Your documents never leave your infrastructure if you use a local RAG setup or a self-hosted vector database. This matters for legal firms, healthcare providers, and finance companies operating under Canadian privacy laws like PIPEDA.
- No retraining required. Add a new document and it becomes searchable within minutes. The model itself does not need to be retrained. This makes enterprise knowledge base integration much faster and cheaper to maintain.
- Works across departments. HR can query policy documents. Sales can query product specs. Legal can query contract archives. One Retrieval-Augmented Generation framework with proper access controls serves the whole company.
The team at Python Technologies has applied this same logic across AI use cases for Canadian businesses in healthcare, legal, financial services, and SaaS.
Vector Databases: The Knowledge Foundation
A vector database stores the embedded chunks from your documents and makes them searchable at speed. Without a vector database, the retrieval step would be too slow for real-time use.
Popular vector databases used in RAG production systems include Pinecone, Weaviate, Qdrant, Chroma, and pgvector (a PostgreSQL extension). The right choice depends on your scale, budget, and whether you need cloud-hosted or self-hosted infrastructure.
For most Canadian small and mid-sized businesses, pgvector running inside an existing PostgreSQL database is the most cost-effective entry point. For enterprise RAG architecture at scale, managed services like Pinecone reduce operational overhead.
The vector database is also where semantic caching for RAG can be applied. Frequently asked questions get their retrieved chunks cached, so the system responds faster and uses fewer API tokens over time.
RAG AI vs Agentic AI: What Is the Difference?
This is one of the most searched questions in Canada right now. The short answer is that these two approaches are not opposites. They are often used together.
RAG AI is about retrieval. It finds the right information and feeds it to a language model so the response is grounded and accurate. It is reactive: the user asks a question, the system retrieves and answers.
Agentic AI is about action. An AI agent can plan, make decisions, call tools, run code, send emails, update records, and complete multi-step tasks on its own. It can also use RAG as one of its tools.
A good way to think about it: Retrieval-Augmented Generation gives the agent memory and knowledge. The agent gives the system the ability to act on what it finds.
Python Technologies builds both. The work on agentic AI services in Canada often starts with RAG as the knowledge layer before adding autonomous action capabilities on top.
If you are looking at whether your use case needs RAG or a full agentic system, the guide on when to upgrade from chatbot to agentic AI lays out the signals clearly.
RAG AI vs MCP: A Quick Comparison
Model Context Protocol (MCP) is a newer standard that lets AI models connect to live data sources, APIs, and tools through a defined interface. The comparison between AI RAG vs MCP comes up often in technical planning conversations.
MCP is a protocol for tool connectivity. RAG is a pattern for knowledge retrieval. They solve different problems.
Use RAG when you need the AI to search through large volumes of unstructured documents, policy files, or knowledge bases and return accurate, cited answers.
Use MCP when you need the AI to connect to live data sources like your CRM, calendar, database, or external API in real time and take action based on current values.
In advanced systems, RAG and MCP are used together. The AI queries live data through MCP and searches document archives through RAG, giving it both real-time situational awareness and deep institutional knowledge.
Types of RAG AI Systems
- The original RAG architecture has evolved significantly. Here are the main types in use today.
- Naive RAG is the simplest form: ingest, embed, retrieve, generate. Good for internal prototypes and small document sets.
- Advanced RAG adds pre-retrieval steps like query rewriting and sub-query decomposition, and post-retrieval steps like reranking and context compression. This is the standard for production systems.
- Modular RAG breaks the pipeline into swappable components. You can replace the embedding model, the retrieval strategy, or the language model independently. This makes upgrades faster without rebuilding the whole system.
- Graph RAG stores relationships between entities, not just chunks of text. If your documents have complex connections between people, products, and events, graph RAG finds multi-hop answers that flat retrieval misses.
- Self-RAG is a model that decides when to retrieve and when to answer from its own weights. It generates retrieval tokens to trigger searches mid-generation. This reduces unnecessary retrievals and speeds up responses on simple questions.
- Corrective RAG checks the quality of retrieved documents before passing them to the generator. If the retrieval quality is low, it expands the search to the web or other sources. This improves reliability significantly for edge-case queries.
- Conversational RAG maintains a history of the conversation so follow-up questions stay in context. Without this, a RAG system treats every message as a new isolated query.
- Multimodal RAG handles images, audio, and video alongside text. This is growing in use for product documentation and technical support systems that include diagrams, screenshots, and video walkthroughs.
How RAG AI Reduces Hallucinations
Hallucination is when an AI confidently states something that is false. It is the biggest trust problem in AI adoption for business.
Retrieval-Augmented Generation reduces hallucination in a direct way: the model is constrained to answer based only on what was retrieved. If the answer is not in the documents, a well-designed RAG system says so, rather than making something up.
This is not a complete guarantee. Poorly configured chunking can cause the model to miss relevant context. Poor retrieval can return the wrong passages. But compared to a standalone language model with no grounding, this approach is significantly more reliable for factual, domain-specific queries.
The combination of hybrid search RAG (dense plus sparse retrieval), a cross encoder reranker, and contextual retrieval RAG techniques brings hallucination rates down further. These are standard components in the systems Python Technologies builds for clients who need verifiable, traceable AI answers.
Choosing the Right Scale in Canada
Small businesses can start with a local RAG setup using open source RAG models like LlamaIndex or LangChain with a lightweight vector store. Cost stays low. A team of five can have an AI assistant that answers questions from their shared drive files within days, not months.
Mid-market companies benefit from managed RAG pipelines with role-based access control, audit logging, and integration with tools like Notion, Confluence, SharePoint, and Salesforce. The knowledge base grows with the business.
Enterprise RAG architecture handles millions of documents with strict security partitioning, enterprise knowledge base integration across business units, and advanced evaluation using frameworks like RAGAS to monitor retrieval quality continuously.
Python Technologies works across all three tiers. The custom AI agents built for GTA businesses often sit on a RAG foundation that gets more sophisticated as the client scales.
Evaluating RAG Systems
How do you know if your RAG system is working well? Evaluation is a step most teams skip and then regret.
The main metrics to track are:
- Context precision: Are the retrieved chunks actually relevant to the question?
- Context recall: Did the system find all the relevant information, or did it miss key passages?
- Answer faithfulness: Does the generated answer stay within what was retrieved, or does it add unsupported claims?
- Answer relevance: Does the answer address what the user actually asked?
RAGAS is one of the most widely used evaluation frameworks for RAG systems. It automates scoring across these dimensions using a separate LLM judge. Running RAGAS on a test set of real user queries before and after each system change tells you whether the changes helped.
Security and Privacy for AI Document Search
Canadian businesses often ask about RAG security before anything else. The concerns are legitimate.
When your documents are embedded into a vector database, someone with the right access can technically reconstruct parts of the original text. This is why access controls at the chunk level are essential, not optional. A legal document should only be retrievable by users with legal access. HR files should not surface for sales queries.
Other important RAG security considerations include secure storage of the vector database, encryption at rest and in transit, audit logging of every query and retrieved chunk, and data residency compliance for businesses that must keep data in Canada.
Python Technologies addresses these in every client implementation. The AI regulations guide for Canada in 2026 covers how these requirements are evolving under post-AIDA frameworks.
Getting Started with RAG AI in Canada
The first step is not technology. It is document inventory. You need to know what files your business has, how current they are, and which departments need to query them.
From there, the implementation path looks like this: choose a language model, choose a vector database, set up your chunking and embedding pipeline, load your documents, test retrieval quality with real questions, and integrate into the tool your team already uses, whether that is Slack, a web portal, or a CRM.
If you want to understand the full cost and timeline before committing, the detailed breakdown on AI agent development cost and timeline in Canada covers what the numbers typically look like for different project scopes.
For businesses ready to start building, the custom software development services at Python Technologies include full RAG pipeline design and delivery.
Frequently Asked Questions About RAG AI
What does RAG AI stand for?
RAG AI stands for Retrieval-Augmented Generation. It is an AI framework that retrieves relevant information from your business documents before generating a response. This grounds the AI in your actual data instead of relying on what it learned during training.
How is RAG AI different from a regular chatbot?
A regular chatbot answers from a fixed script or from what the AI model was trained on. A Retrieval-Augmented Generation system searches your actual business documents in real time and generates answers from that content. It can answer questions about your policies, products, contracts, and records in a way a standard chatbot cannot.
Do I need to retrain the AI model to add new documents?
No. One of the biggest advantages of this framework is that new documents become searchable as soon as they are ingested and embedded. There is no model retraining required. You add a file and the AI can use it within minutes.
What types of documents can this AI framework handle?
It can work with PDFs, Word documents, Excel files, text files, Confluence pages, Notion databases, SharePoint libraries, email threads, Slack channels, CRM notes, and more. Any text-based content can be ingested, chunked, and made searchable.
How does Retrieval-Augmented Generation reduce hallucinations?
It reduces hallucinations by constraining the language model to answer from retrieved content only. Instead of generating from memory, the model reads specific chunks of your documents and bases its response on them. A well-configured reranking step ensures the model gets the most relevant chunks, which further reduces the chance of a grounded error.
Is this AI system secure for sensitive business data?
Yes, when implemented correctly. Enterprise RAG architecture uses chunk-level access controls, encrypted vector storage, audit logs, and data residency configurations. Businesses in regulated industries like healthcare and finance can run this framework without sensitive data leaving their own infrastructure.
What is the difference between RAG AI and agentic AI?
Retrieval-Augmented Generation is a knowledge retrieval pattern. Agentic AI is a system that can plan and take actions. The two are often combined: a retrieval layer provides the knowledge base and an agentic layer uses that knowledge to complete tasks, send messages, update systems, or make decisions autonomously.
How much does it cost to build a RAG AI system in Canada?
Costs vary widely based on document volume, infrastructure choices, and integration complexity. A simple internal knowledge base assistant for a small team can be built for a few thousand dollars. An enterprise RAG architecture with security controls, evaluation pipelines, and integration across multiple systems ranges higher. Python Technologies provides detailed scoping and cost estimates before any project starts.
Quick Reference: Key Terms Explained
Term | What It Means |
Chunking | Breaking documents into smaller pieces for retrieval |
Embedding | Converting text to numerical vectors for similarity search |
Vector database | Stores embeddings and enables fast semantic search |
Hybrid search | Combines dense vector search and keyword search for better recall |
Reranker | A second-stage model that sorts retrieved chunks by relevance |
RAG pipeline | The full sequence from ingestion to generated answer |
Hallucination | When an AI states something false without a source |
RAGAS | A framework for automatically evaluating RAG quality |
Python Technologies builds RAG AI systems for businesses across Canada, including Toronto, Ottawa, Vancouver, and Calgary. If you are exploring whether a Retrieval-Augmented Generation framework is the right fit for your team, the contact page is the fastest way to start a conversation.
For more on where AI is heading and how it connects to the systems you are building now, the overview on agentic AI in 2026 gives the full picture of what is possible beyond RAG alone.
About
Menu
Locations
© 2026 – Python Technologies. All Rights Reserved.